Blog
Democratizing AI Compute Series
Go behind the scenes of the AI industry with Chris Lattner
Latest
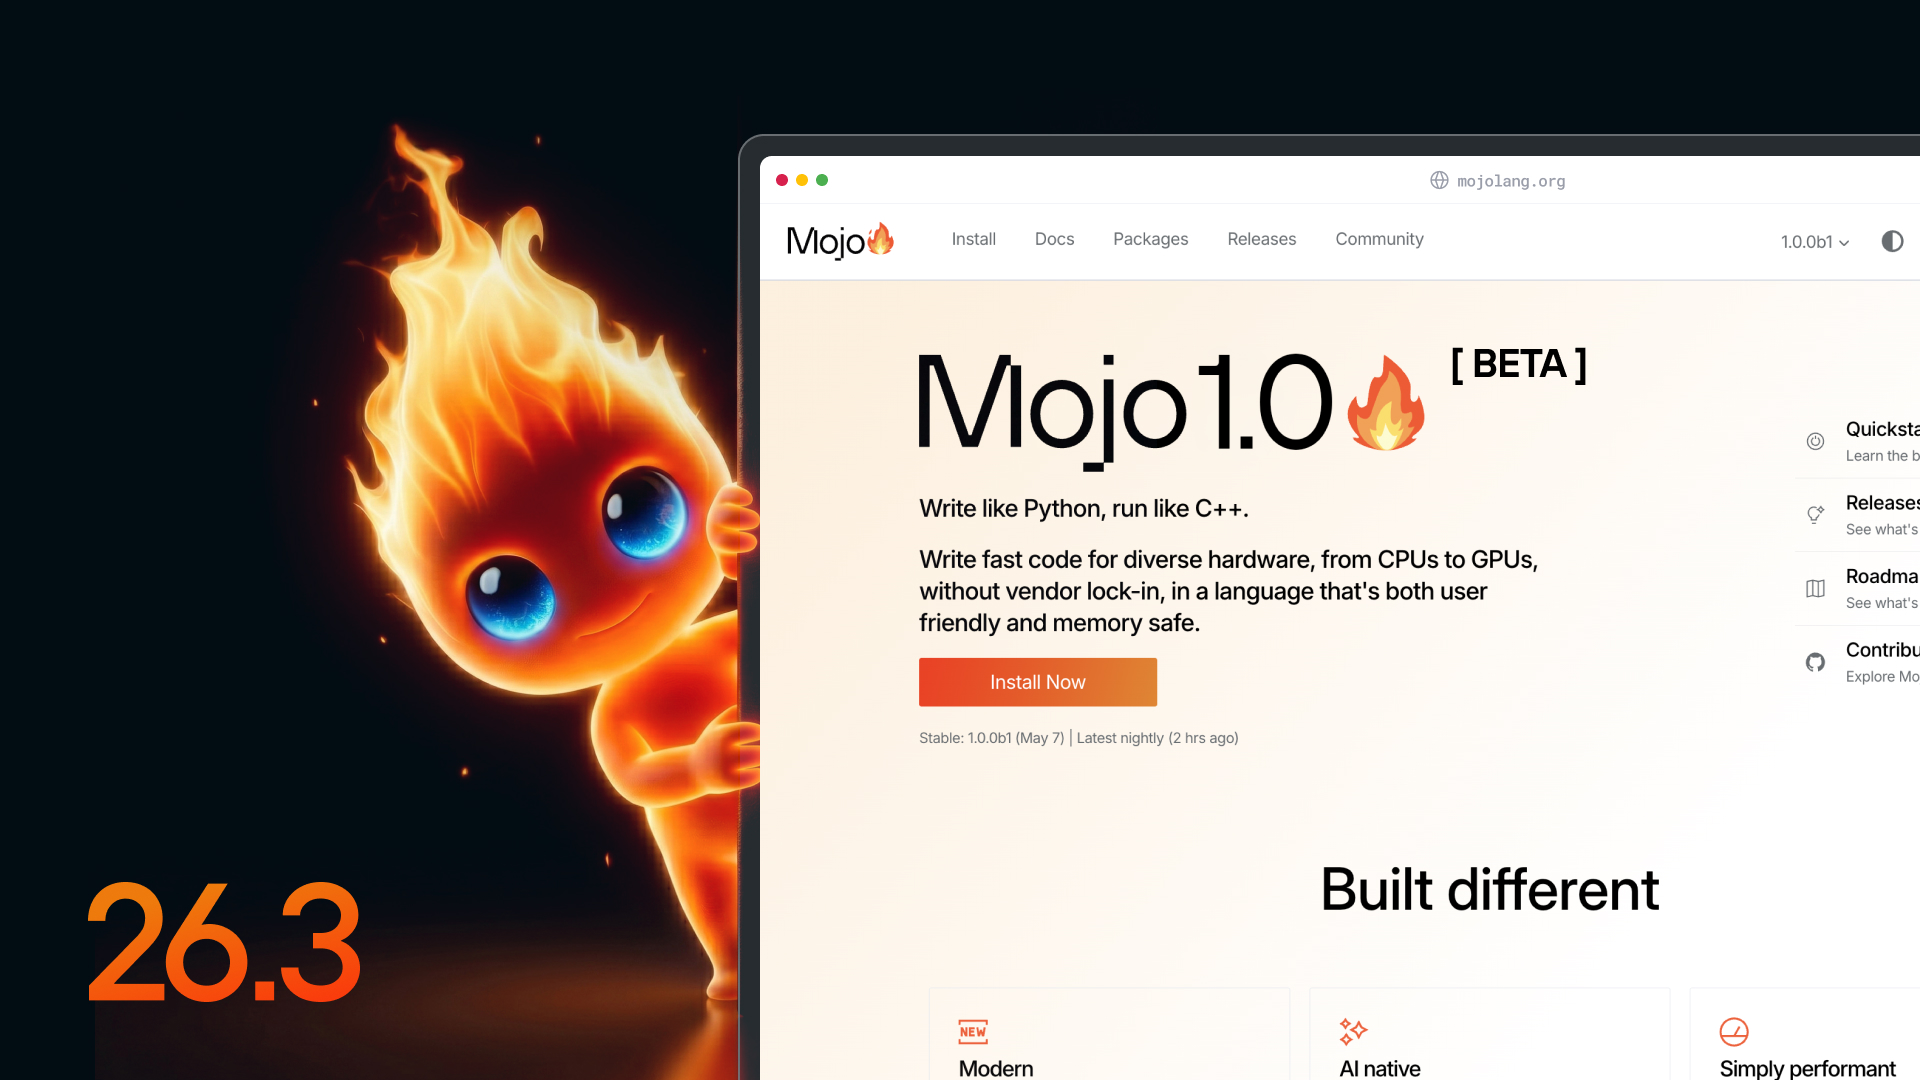
Modular 26.3: Mojo 1.0 Beta, MAX Video Gen, and more
Surprise: Mojo 1.0 is officially in beta! Modular’s 26.3 release includes new features and modalities, but the headline is that we’ve officially hit beta for Mojo 1.0, with a clear plan to finalize Mojo 1.0 in the coming months. We share details below, alongside other key announcements in our 26.3 release including video generation in MAX with Wan 2.2 and MAX framework updates.
Modverse #54: AMD AI DevDay, New Modular Offices, and a Community That Keeps Shipping
There was a lot to celebrate in April: the community shipped GPU renderers, FFmpeg bindings, raylib wrappers, BLAS routines, and a 2D graphics API, just to name a few. The team connected with tons of developers at AMD AI DevDay and our joint meetup with AMD, two new Modular offices opened on two different continents, and Gemma 4 launched with same-day support on NVIDIA and AMD. Here’s the April roundup.
TileTensor Part 1 - Safer, More Efficient GPU Kernels
Suppose you want to load a 2D tile of a matrix, where the tile is stored in shared memory in a specific interleaved layout to avoid bank conflicts. This example uses a toy XOR swizzle to illustrate the class of bugs; real kernels use hardware- and layout-specific swizzles and vectorized accesses. Without a layout abstraction, here is how you would launch a kernel with a block size of (32,8):
Structured Mojo Kernels Part 4 - Portability and the Road Ahead
GPU portability has a mixed track record. “Write once, run everywhere” usually means “write once, run slowly everywhere.” CUTLASS does not attempt portability beyond NVIDIA hardware and is usually limited within a generation of the hardware. Triton provides portability but performance degrades on non-NVIDIA targets. The conventional wisdom is that you have to choose between being portable or being fast.
Modverse #54: From GTC to Edinburgh, a Community Building Momentum
This edition covers one of the busiest stretches in Modular's recent history: four days at GTC, a new office on another continent, fresh community builds, and a release that expands what MAX and Mojo🔥 can do. Here's everything that's been happening across the ecosystem.
Software Pipelining for GPU Kernels: Part 1 - The Pipeline Problem
Flash Attention is a simple algorithm: tiled back-to-back matmuls with an online softmax algorithm in between. The algorithm fits in a few dozen lines of pseudocode. Yet Flash Attention 4's production kernel is 2,875 lines, and the hardest part to get right isn't the math. It's the async execution and pipelining synchronization, all hand-derived from a schedule that no standard debugging tool can verify.
Structured Mojo Kernels Part 3 - Composition in Practice
This post shows the practical benefit of this modular design. We take two real kernel families, conv2d and block-scaled matmul, and trace exactly how they are built around the matmul foundation. In both cases, a new kernel family requires changing one component while leaving the rest untouched. The conv2d kernel adds roughly 130 lines of new code, whileBlock-scaled matmul adds roughly 200 with no performance degradation.
No items found within this category
We couldn’t find anything. Try changing or resetting your filters.

Sign up today
Signup to our Cloud Platform today to get started easily.
Sign Up
Browse open models
Browse our model catalog, or deploy your own custom model
Browse models